

Where I started
I’m a backend engineer on MCode, MiniMax’s coding agent, which has a desktop app and a terminal UI. Nearly all my coding goes through agents, and MCode comes first: I work on it, so it’s what I use for my own work every day. I also keep Codex and Claude Code around, to cross-check work and see how they handle the same task. To get more done, I wrote Agent Lord, an orchestrator that lets one agent session hand work to others. From a Codex session, it split a feature into modules and sent each module to its own CLI, usually MCode, in its own git worktree. Modules that didn’t depend on each other ran at the same time. For reviews, two model families checked each other’s findings. At the end, an integrator merged everything. In the month I later measured, it dispatched 490 operations across 214 tasks. The bet was simple: more agents working at once, more work done. By mid-September it didn’t feel that way. Here’s what I typed to my agents in a single day:“This is so tedious. Everything takes forever to build.”
“Do we really need this many tickets? Can’t we merge some?”
“It’s been reading for an hour.”
“Why not send out more agents? If they don’t depend on each other, why can’t they all go at once?”
More agents weren’t the answer
That last message was what I believed at the time: the fix was more parallelism. So after Agent Lord spent a night building a new version of MCode’s Goal feature in eight modules, I had an agent audit the run and tell me why so little of it ran in parallel.- At most four CLIs ran at once; the average was 1.27.
- Agent Lord didn’t cap parallelism. The plan did: the modules formed a chain, and each one waited for the one before it to be delivered.
- Waiting didn’t even help. A downstream module still started from the original code, so it couldn’t see what its upstream had just written. It coded against stubs, and the real pieces met for the first time at the final merge.
- Inside each CLI, most of the time went to waiting on the model, usually with one tool call per turn. One module made 91 round trips, about 56 minutes, before it wrote its first file.
What was actually wrong
The next day I had agents go through every session from the previous 30 days, about 1,700 across MCode, Codex and Claude Code, to see whether that run was a one-off. They read 40 task chains closely and checked the quotes against the raw logs. It wasn’t a one-off. Two problems ran through the whole month. Bugs showed up late, and I was the one who found them. The agent said it was done and the tests passed. The problem appeared when I used the feature myself, or when the pieces were wired together.- The agent marked two PRs for the Goal feature done, tests green. I ran the dev build. If I updated the goal while the agent was waiting on background work, it never picked the work back up.
- The status bar said reasoning effort was xhigh. The session actually ran at medium, because new sessions never passed the setting through.
- Every module of the Goal rework was delivered, and the feature still wasn’t turned on in the default production setup.
- I settled MCode’s four sandbox permission levels in August. In September I was still telling agents: four levels, no extra protections.
- My main session handed a plan to another CLI for cross-review and added “keep it concise” on its own. The 875-line plan was replaced by a 279-line one that had lost the file-by-file migration table, the interfaces, the wiring steps and the acceptance checks.
- I asked for a PR based on the latest integration branch. It was opened against a feature branch, and fixing it meant a rebase and three merge conflicts.
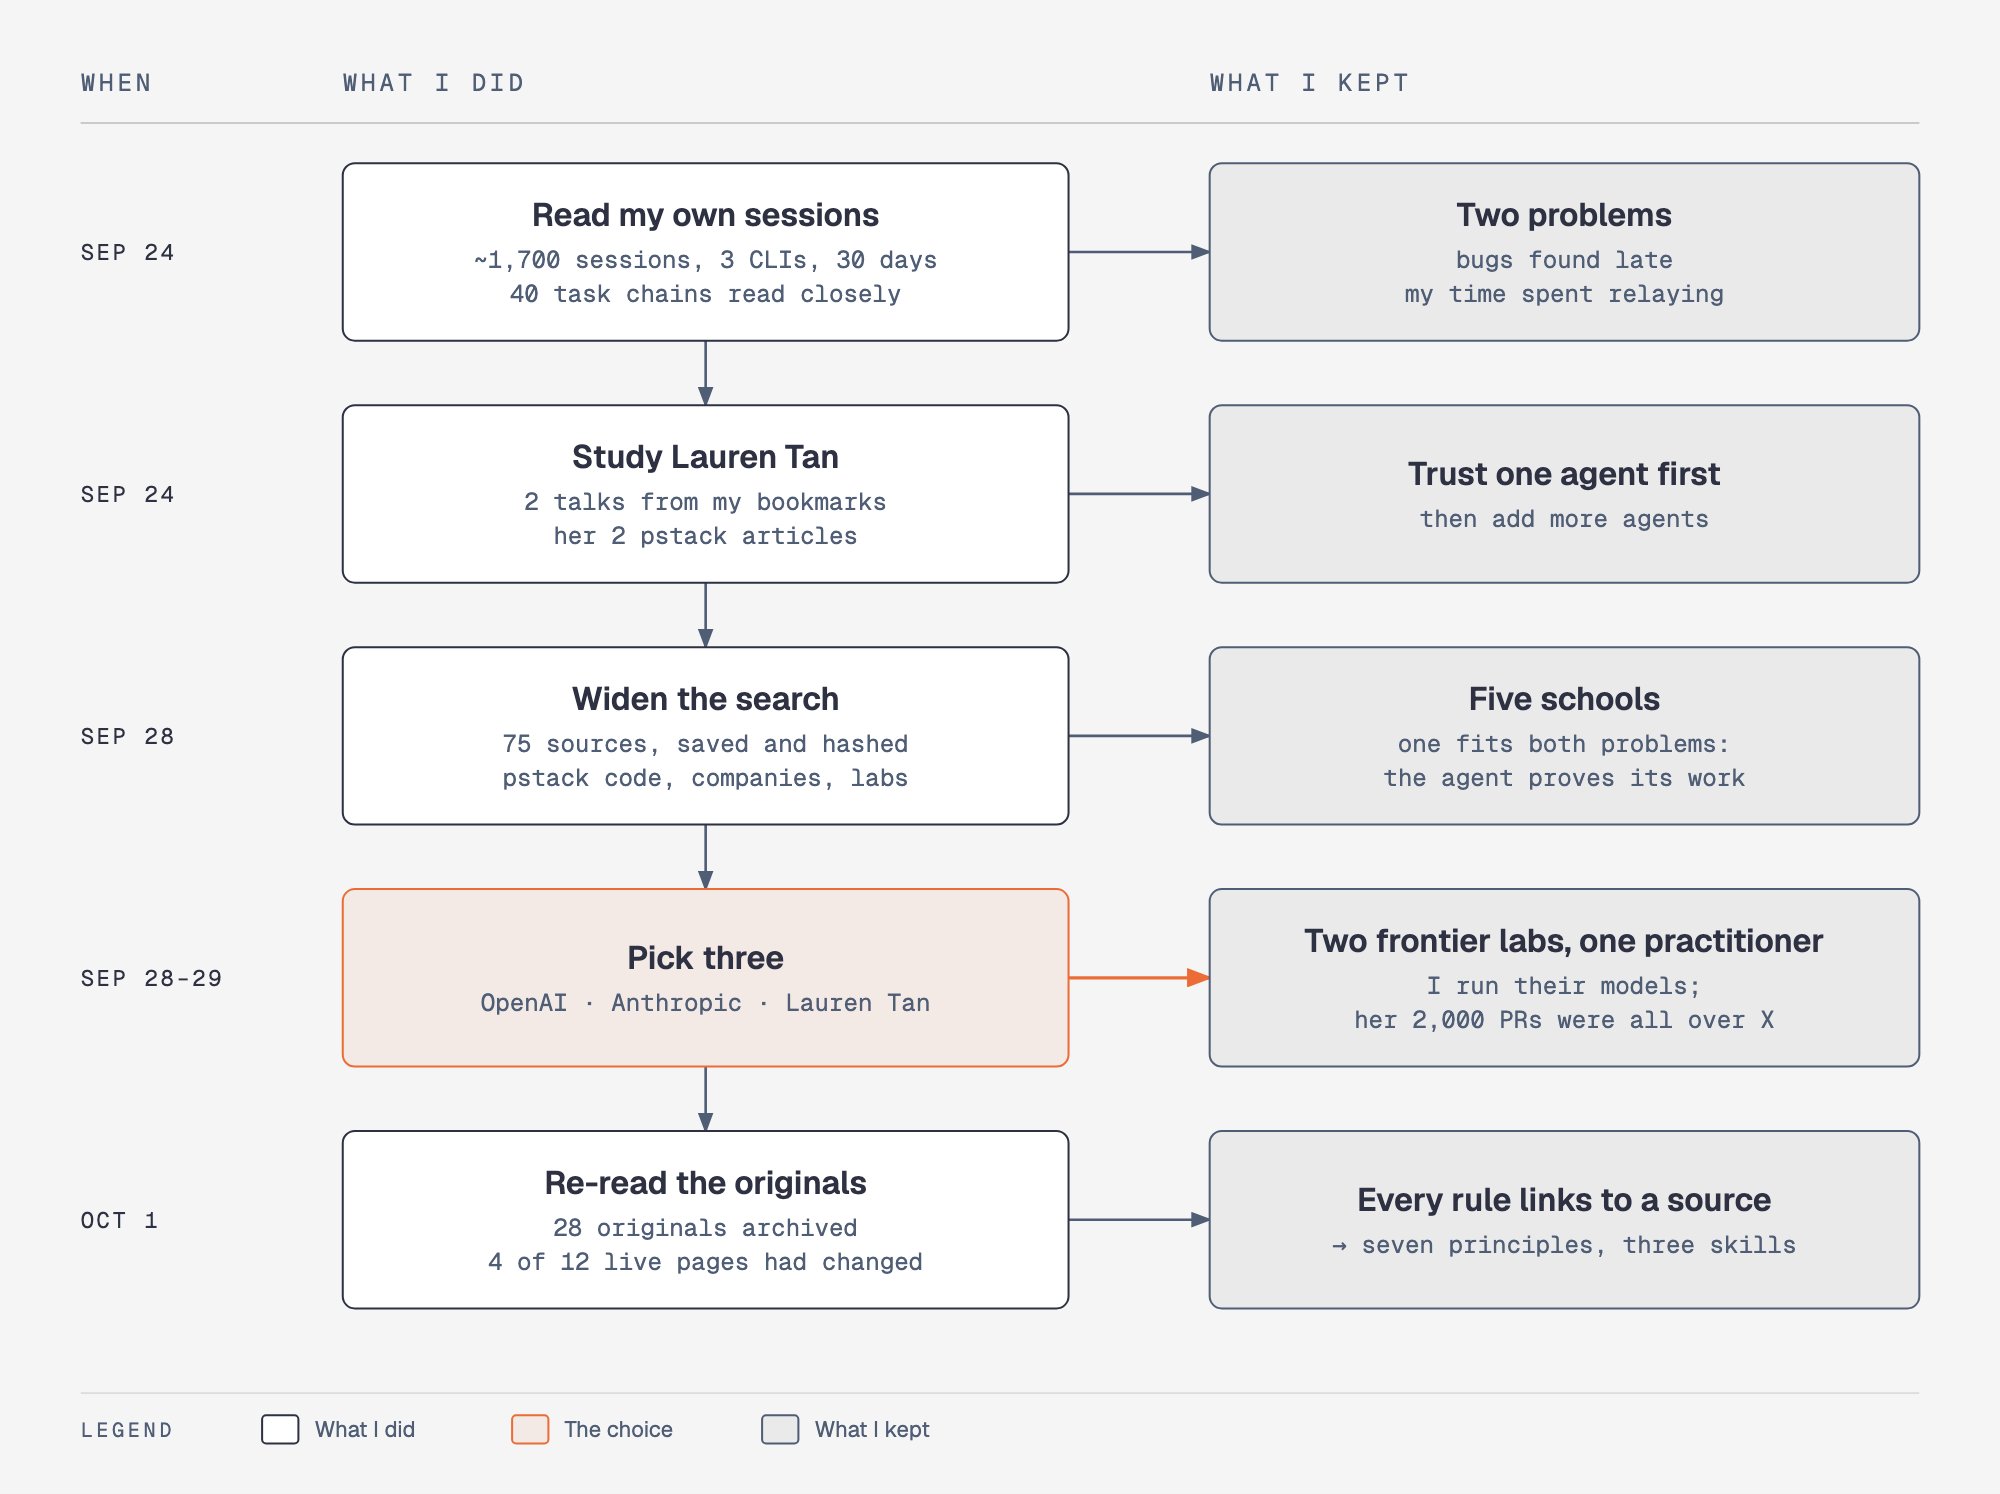
How I picked the three sources
The workflow at a glance
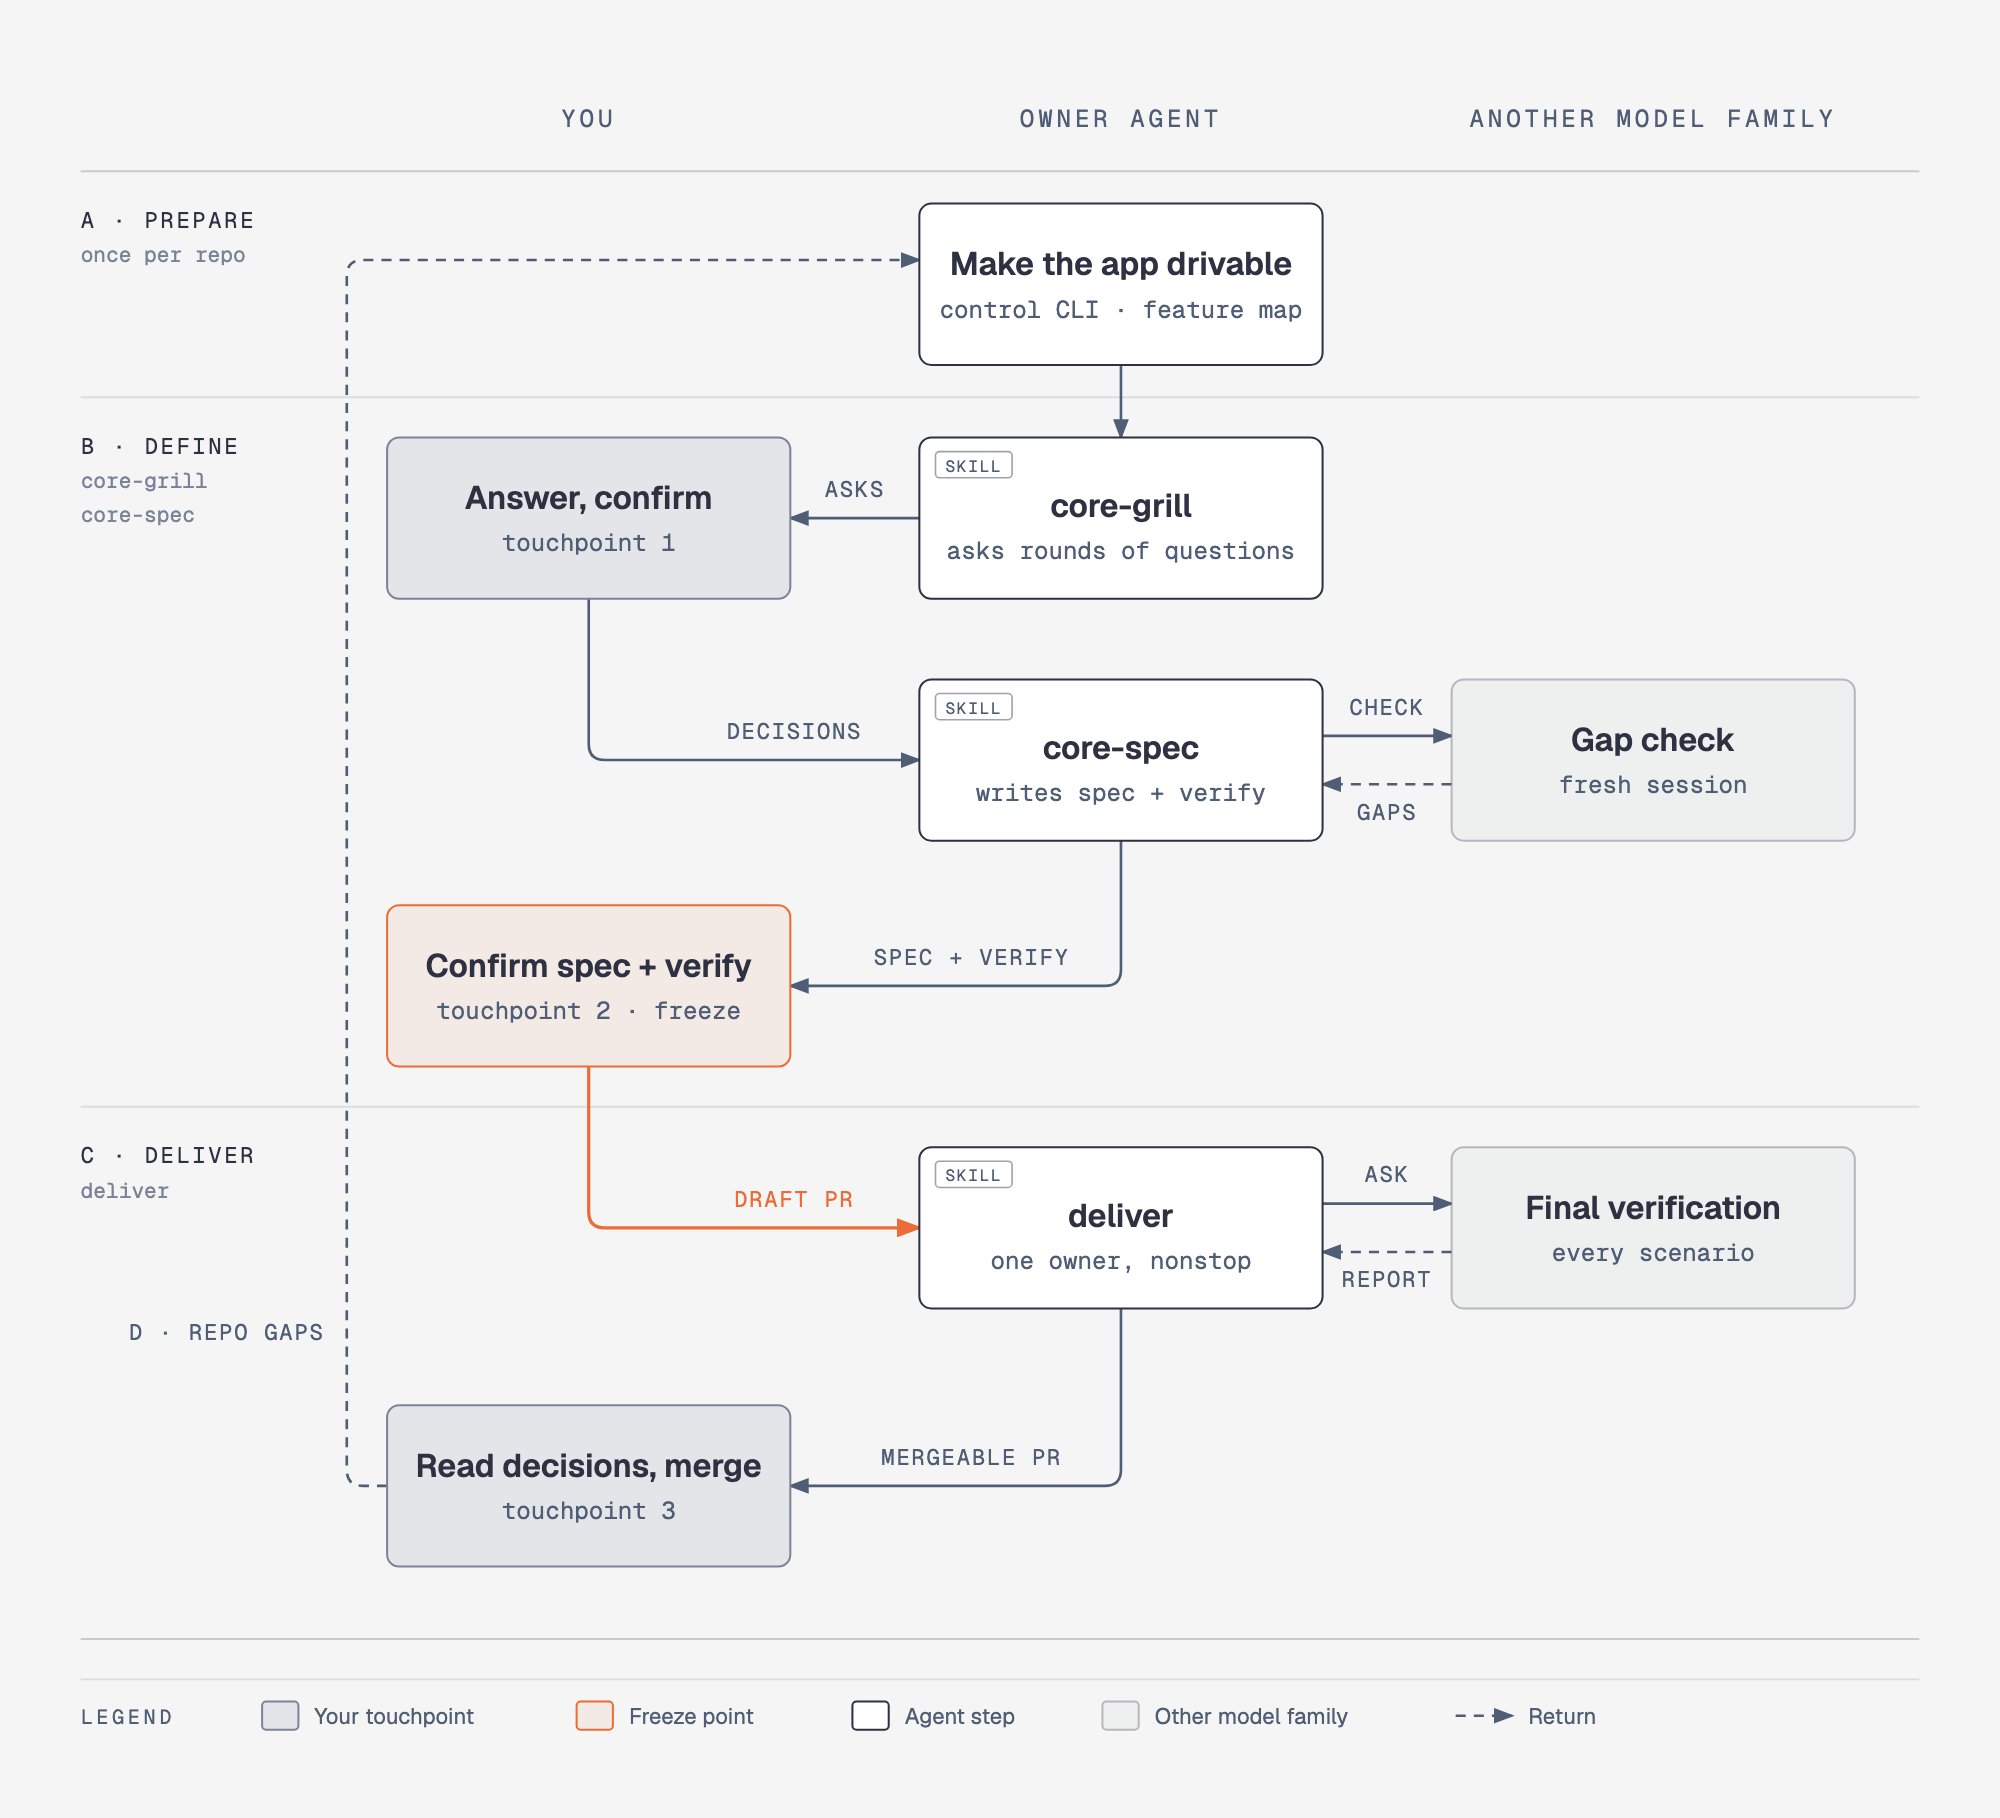
core-grill clarifies the request; core-spec records the decisions and how to verify them. Another model family checks for gaps. I confirm the files, which are frozen on a feature branch with a draft PR.
C. Deliver (the agent alone). In a new session I run /deliver <draft PR link>. One owner builds and tests the feature, coordinates independent checks, and handles CI and review until the PR is mergeable. It pauses before irreversible actions and records its decisions for me to review.
D. Feed back. The PR lists gaps this run exposed in the repo. I decide which fixes belong in the repo’s tools and which belong in the skills.
My part comes down to three touchpoints: answer the questions, confirm spec.md and verify.md, then read the decision list and merge.
The three skills
core-grill: ask only about what users will see
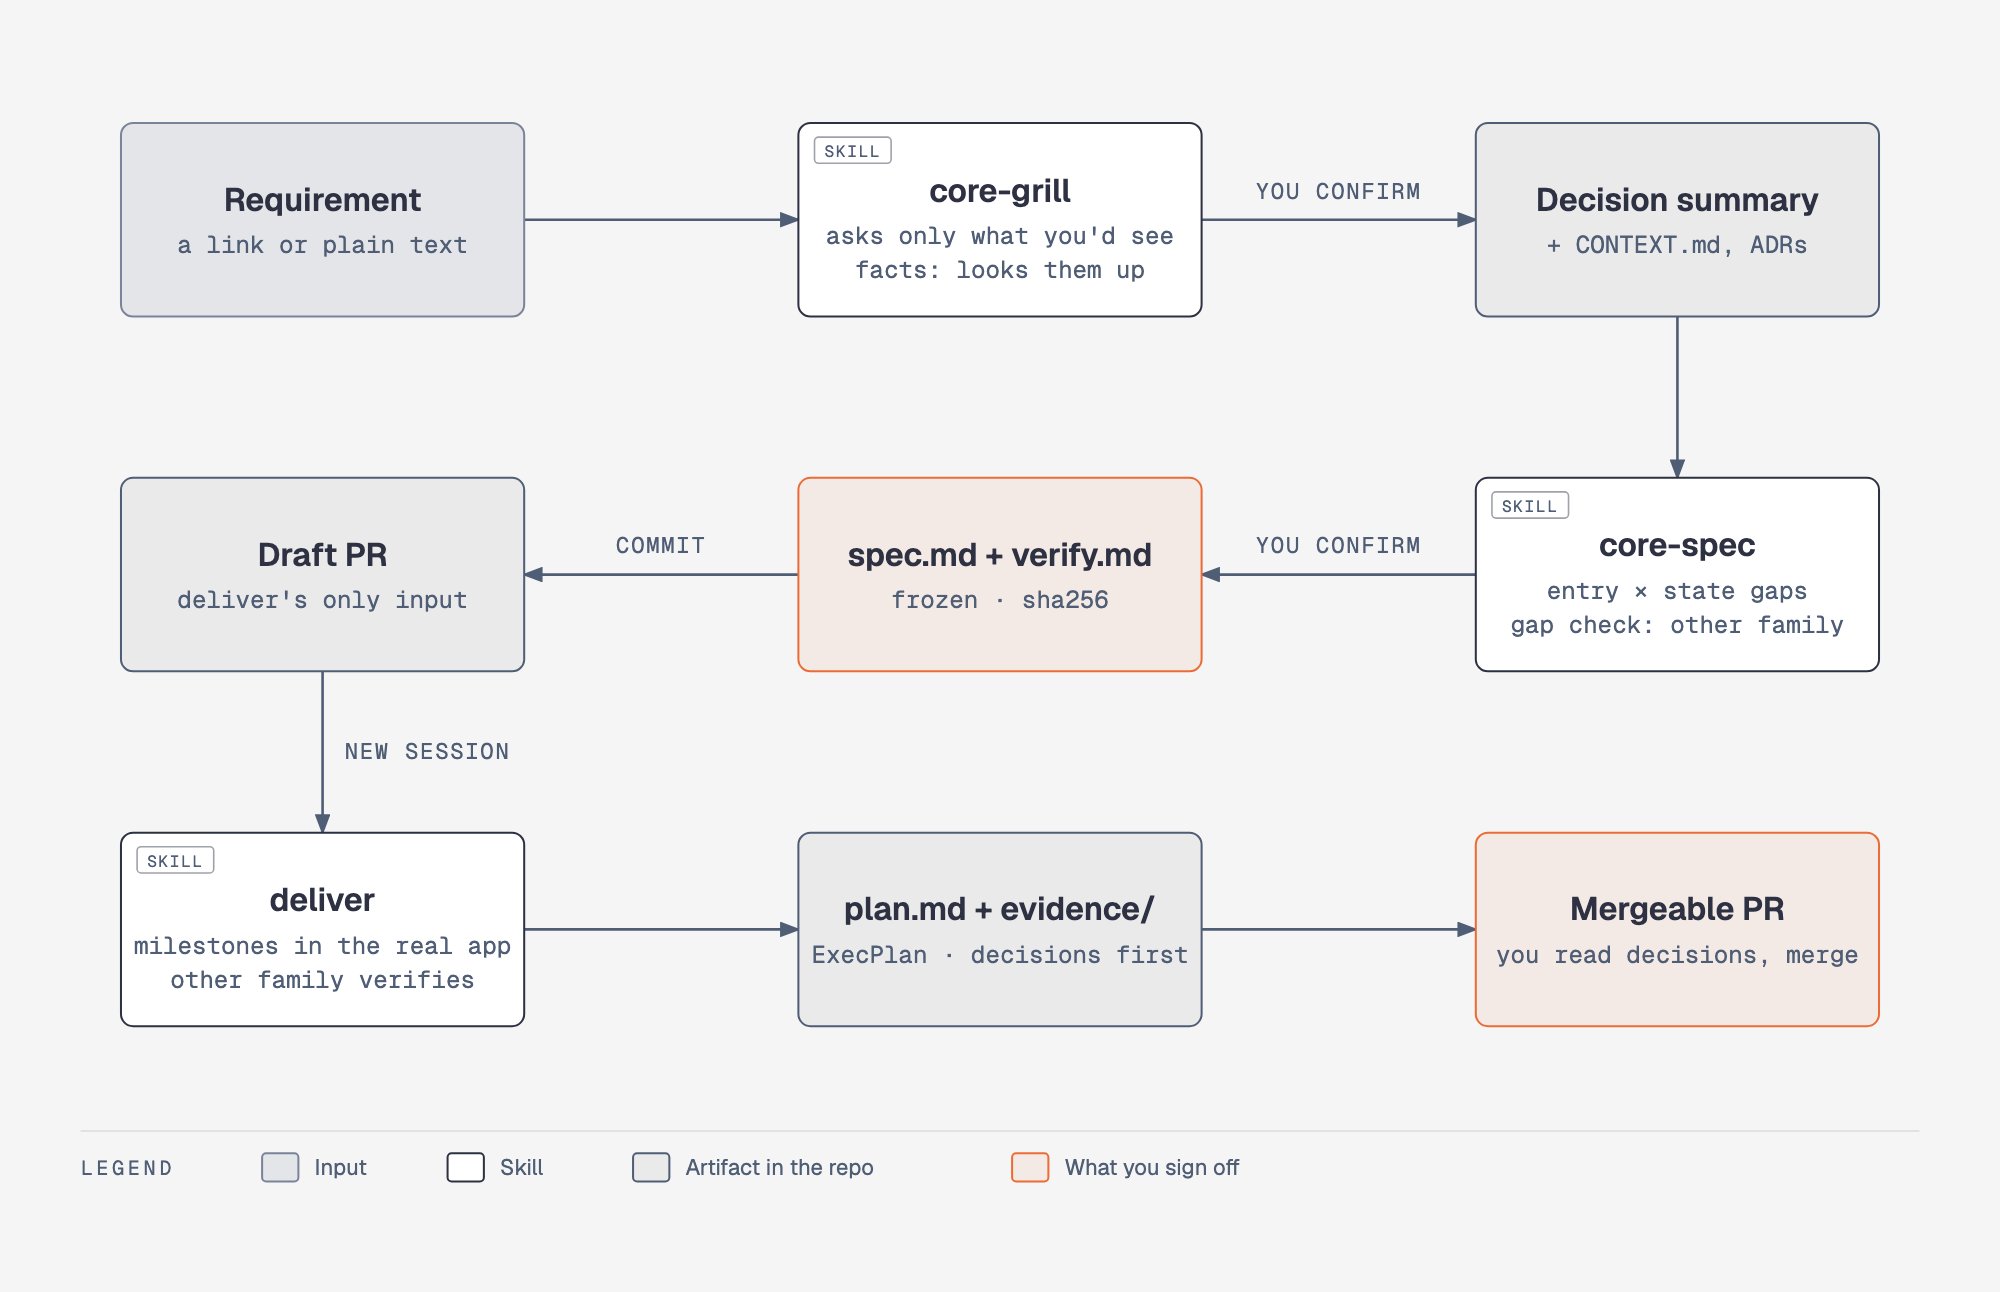
It starts with the request, the goal, what “done” means, and what it’s allowed to do. If the repo can answer a question, it looks there first. It asks me about choices that change what users see: behavior, copy, defaults, entry points and whether data can be lost. Each question includes options, consequences and a recommendation. It handles implementation choices itself and records the defaults. I confirm the resulting decision summary.core-spec: two files, checked by another model, then frozen
It turns that summary intospec.md (what we decided) and verify.md (how to prove it).
The useful part is writing the checks before the code. Each scenario follows a complete user action from a real entry point and says what should happen on the old code. If that baseline wouldn’t expose the risk, it also describes a wrong implementation the check must reject. This forces gaps in the spec to surface early.
Another model family reviews both files in a fresh, read-only session, without the author’s reasoning. If that reviewer is unavailable, the files don’t get frozen. Once the gaps are resolved and I confirm, both files are frozen and committed, and a draft PR is opened. That link is all deliver needs.
deliver: one owner until the PR is mergeable
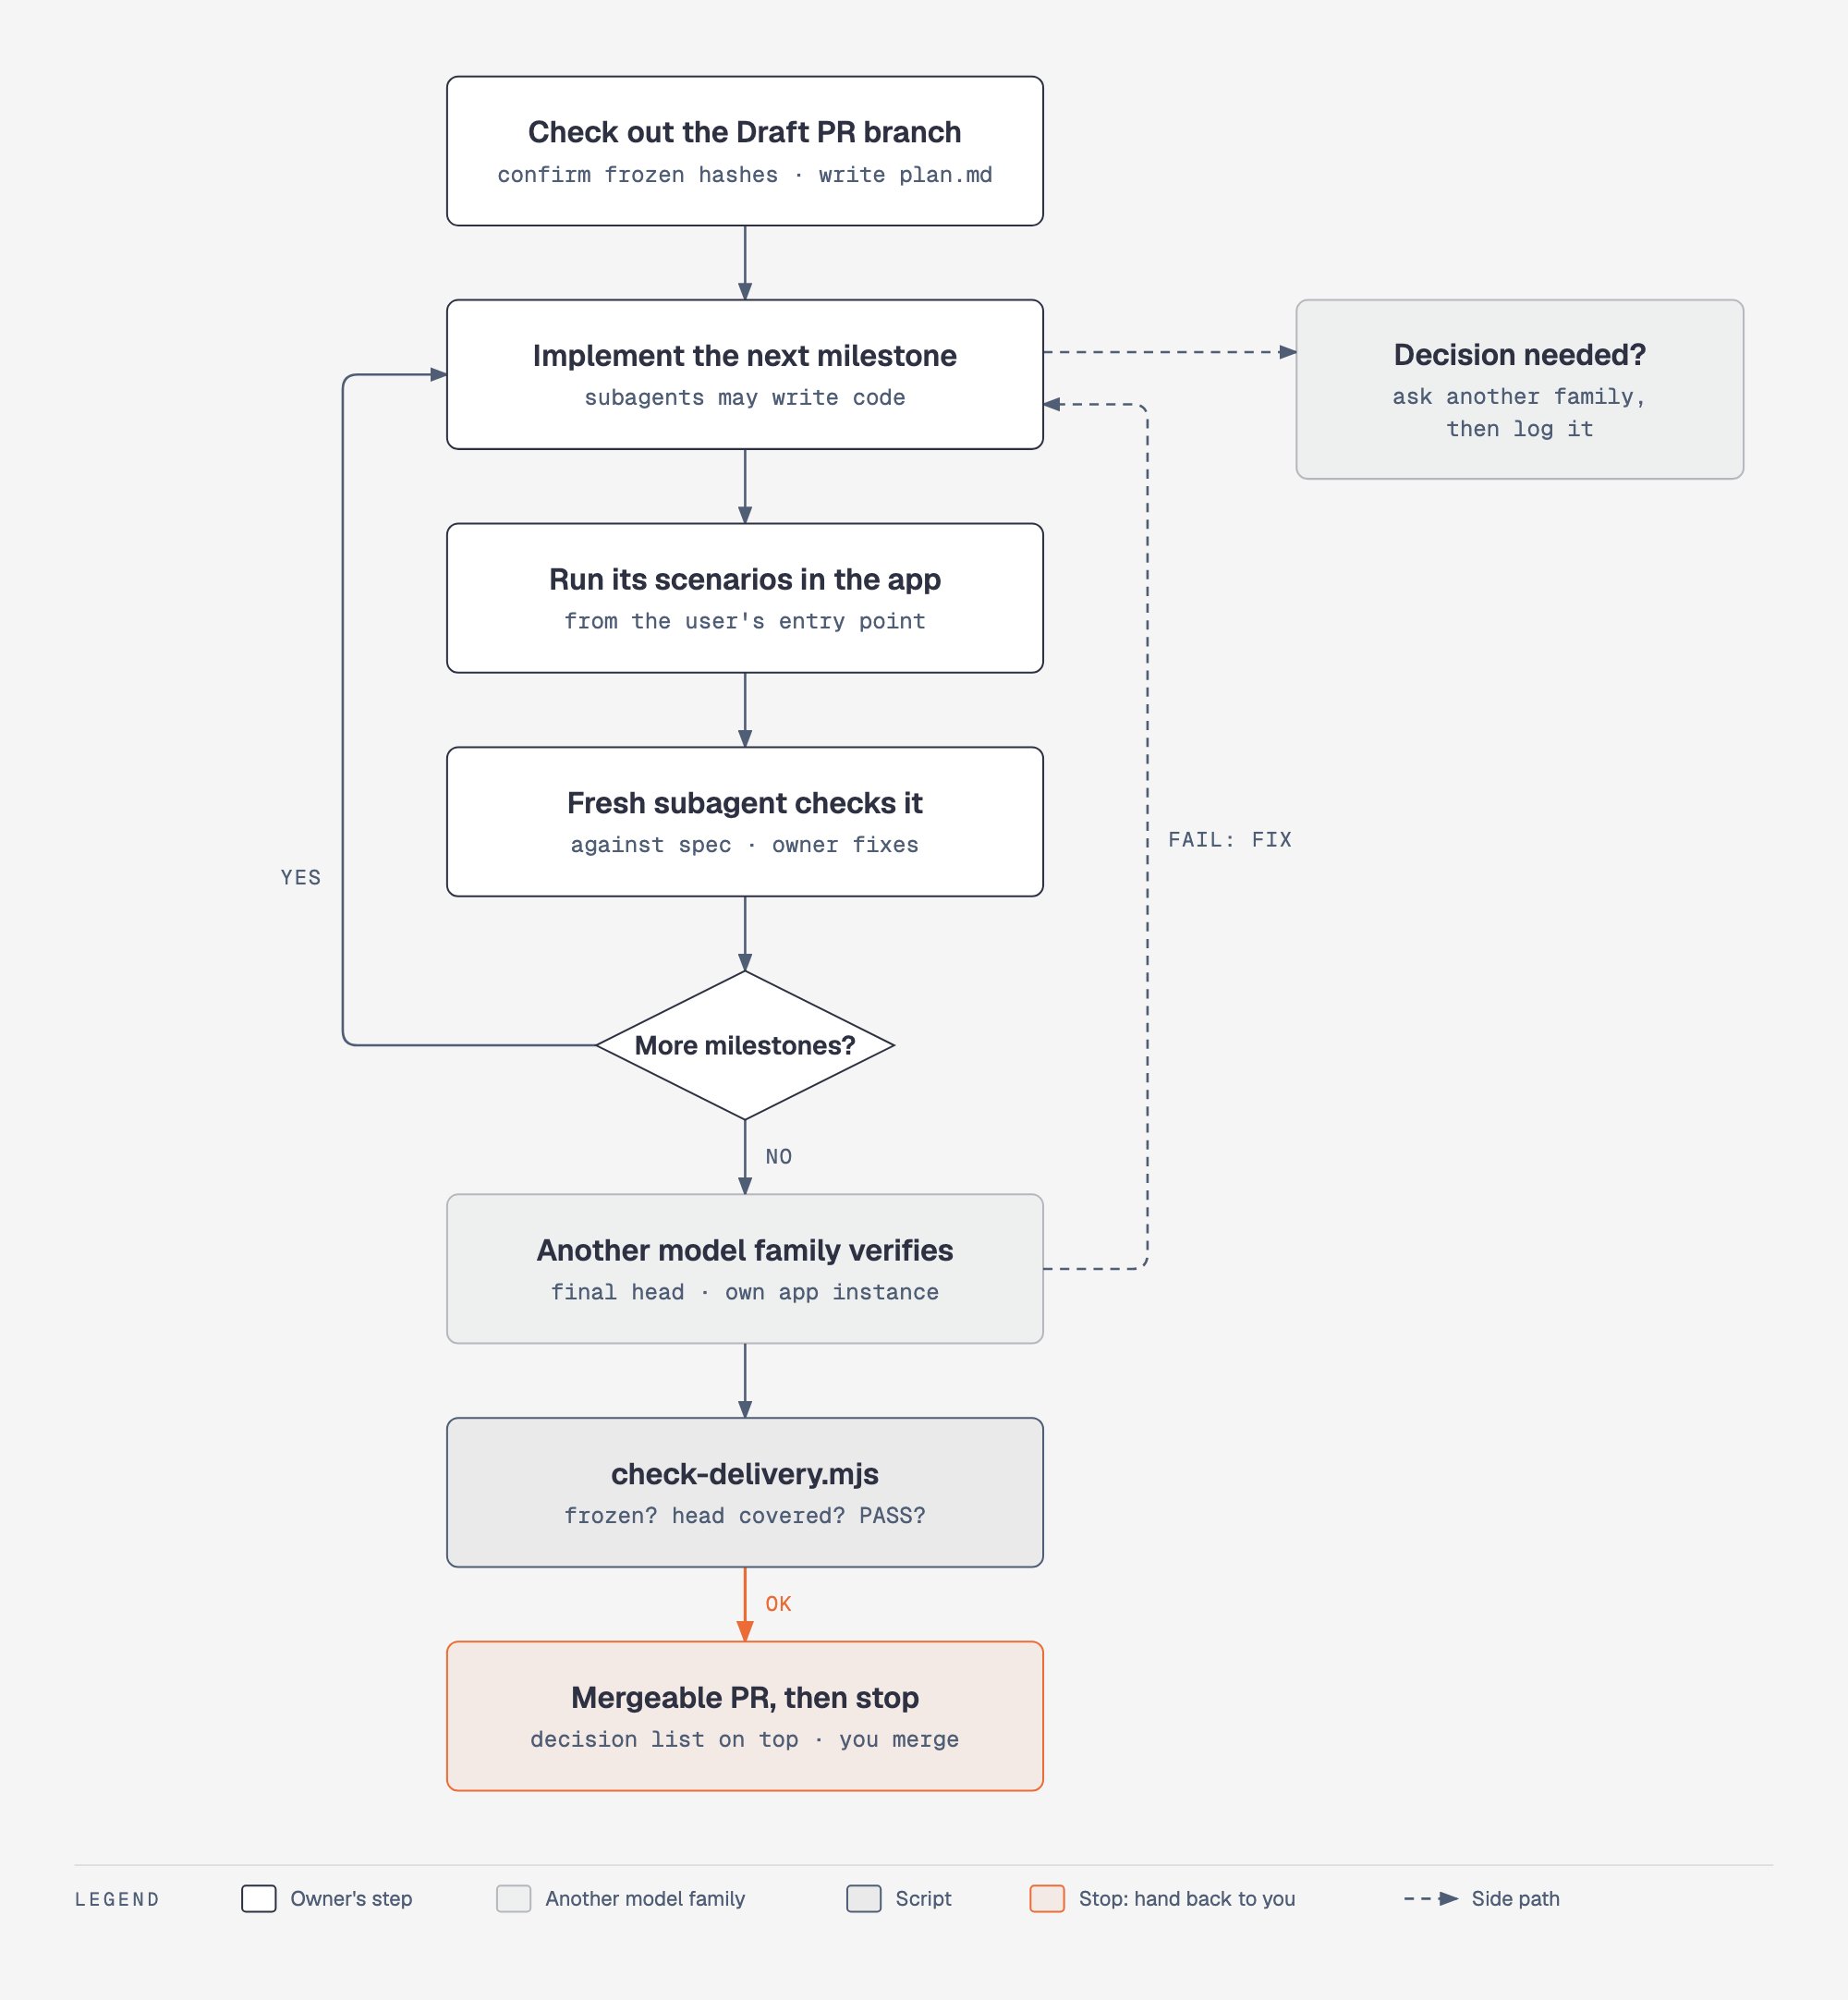
plan.md in OpenAI’s ExecPlan format, committed with the code so a new session can pick up the work.
- Build and prove each milestone. Implement it, run its scenarios on the real app, fix failures, then have a fresh subagent check it against the spec.
- Get another model’s view on decisions. For choices affecting users or how a check is judged, consult another model family without sharing the owner’s preference. Then decide and continue.
- Make those decisions reviewable. Put them at the top of the PR, including gaps, deviations in verification and anything unfinished. Each entry says what must be redone if I overturn it. The frozen spec and verify files stay unchanged.
- Get independent final verification. Another model family checks the final code in its own session and app instance. The owner addresses its code-quality notes or explains why it didn’t.
Who checks what
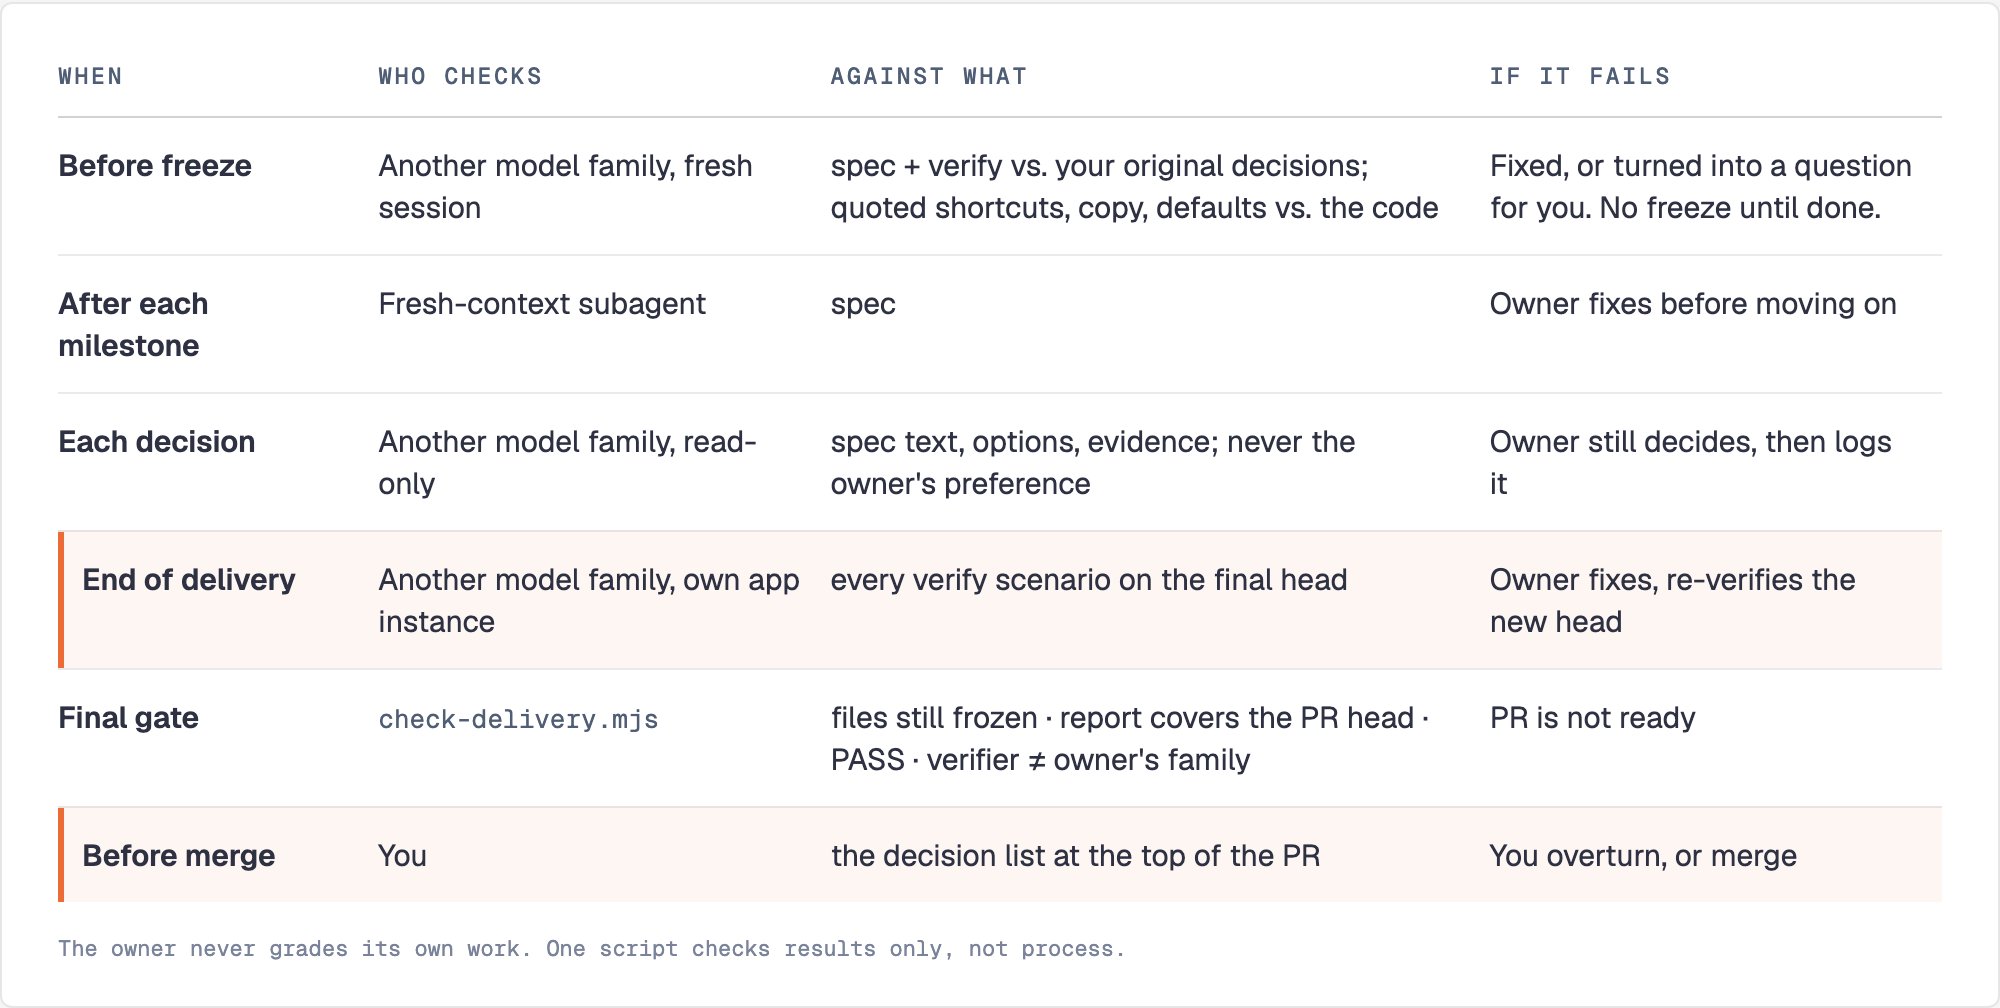
check-delivery.mjs enforces four conditions:
- spec.md and verify.md are still the versions I confirmed;
- the verification report covers the code being merged;
- the verdict is PASS;
- the verifier comes from a different model family than the owner.
The seven principles
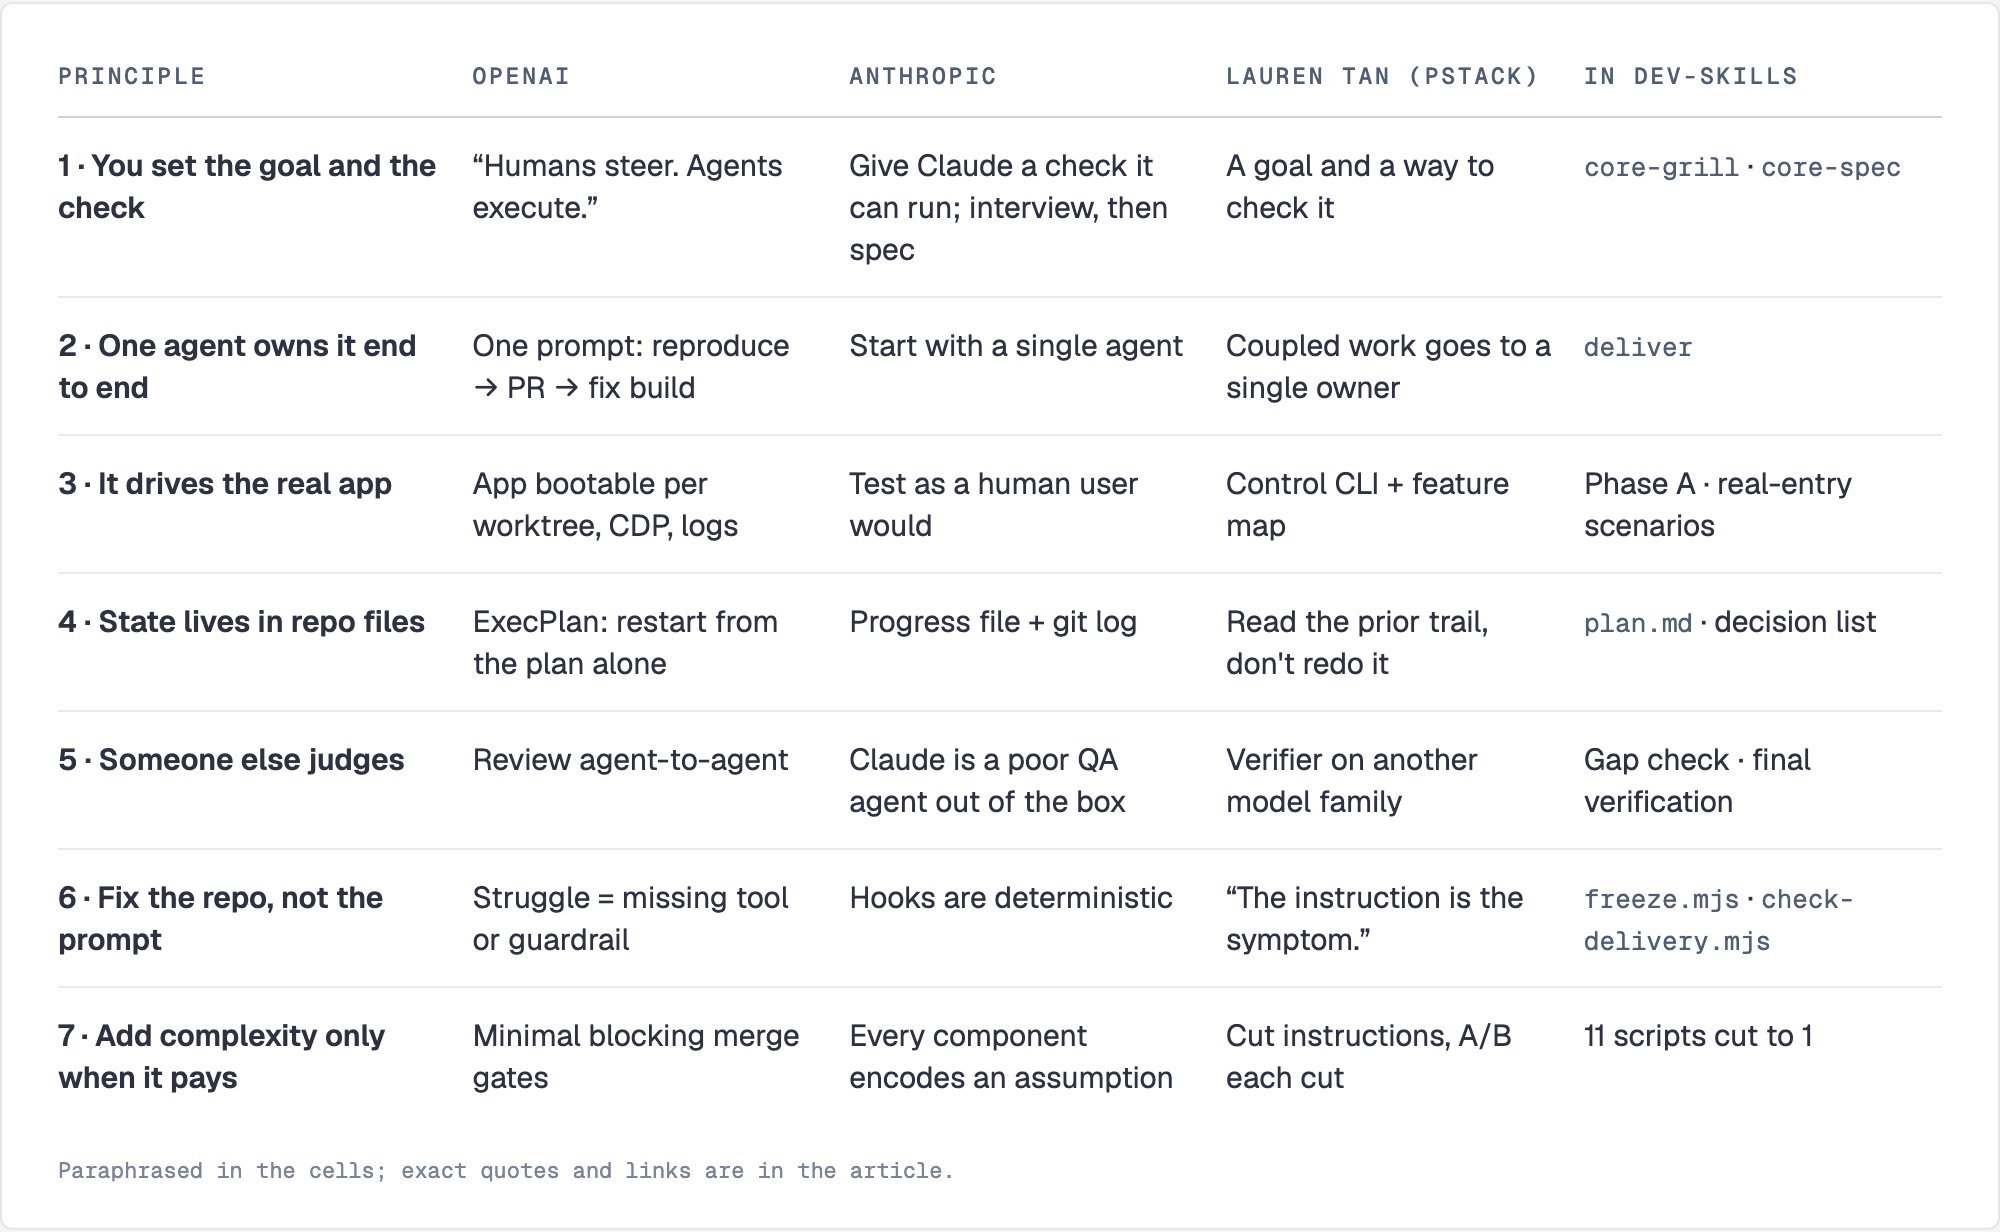
1. You set the goal and the check, then step away
- OpenAI: “Humans steer. Agents execute.” (Harness engineering)
- Anthropic: “Give Claude a check it can run… It’s the difference between a session you watch and one you walk away from.” (Claude Code best practices)
- Lauren Tan: “Give the agent a goal and a way to check it, in your own words.” (pstack guide)
2. One agent owns the work end to end
- OpenAI: in their own repo, given a single prompt, “the agent can now” go from reproducing a bug to merging the fix, and “escalate to a human only when judgment is required.” (Harness engineering)
- Anthropic: “A well-designed single agent with appropriate tools can accomplish far more than many developers expect.” (Building multi-agent systems)
- Lauren Tan: “Code-coupled work (one feature, one migration) goes to a single owner.” (pstack playbooks)
deliver: the owner can hand coding, checks or scenario runs to subagents, but it integrates the work and makes the calls. That’s why I set Agent Lord aside. Work still happens in parallel, but one owner coordinates it.
3. The agent can run, operate and observe the real product
- OpenAI: “we made the app bootable per git worktree, so Codex could launch and drive one instance per change.” (Harness engineering)
- Anthropic: left to itself, their agent passed unit tests without noticing the feature didn’t work end to end. It did much better once told to “do all testing as a human user would.” (Effective harnesses for long-running agents)
- Lauren Tan: a verification skill is “critical infrastructure rather than ‘just’ a skill.” (The Complete Guide to pstack, Pt. 1)
4. Plans and progress live in files in the repo
- OpenAI: “It should always be possible to restart from only the ExecPlan.” (Using PLANS.md for multi-hour problem solving)
- Anthropic: “compaction isn’t sufficient.” Each session starts by reading a progress file and the git log. (Effective harnesses)
- Lauren Tan: “Read the prior trail, don’t redo it.” (pstack playbooks)
deliver keeps plan.md in ExecPlan format, committed with the code. When an upstream API error killed one of my long-running deliveries in Claude Code, I picked it up in MCode: a fresh session read plan.md and the git history and found where it had stopped in under half an hour.
5. Someone else decides whether it’s right
- Anthropic: “Out of the box, Claude is a poor QA agent.” Their fix: “Separating the agent doing the work from the agent judging it proves to be a strong lever.” (Harness design for long-running application development)
- OpenAI: “we’ve pushed almost all review effort towards being handled agent-to-agent.” (Harness engineering)
- Lauren Tan: “Run a unit’s verifier on a different model family from its worker.” (pstack skills)
6. When the agent gets stuck, fix the repo, not the prompt
- OpenAI: “When the agent struggles, we treat it as a signal: identify what is missing—tools, guardrails, documentation—and feed it back into the repository.” (Harness engineering)
- Anthropic: CLAUDE.md instructions “are advisory,” while hooks “are deterministic and guarantee the action happens.” (Claude Code best practices)
- Lauren Tan: “The instruction is the symptom.” (Encode Lessons in Structure)
freeze.mjs pins spec.md and verify.md, and check-delivery.mjs gates the result. Phase D turns each run’s friction into repo tooling.
7. Add complexity only when it pays, one piece at a time
- Anthropic: they recommend “finding the simplest solution possible, and only increasing complexity when needed.” (Building effective agents)
- OpenAI: “Prefer a narrow correction to accumulating universal rules for every observed example.” (Codex skill-creator)
- Lauren Tan: pstack PR #419 cut 19 instructions. “Each cut held up in A/B runs on tasks that exercise it, with and without the text.” (PR #419)
deliver went from 3 scripts to 11, and its instructions grew by about 70%. Then I cut back to 1 script and less than half the instructions. The whole arc took 32 versions of the workflow in four days.
How to use it
What you need- Models from two families. I develop in MCode and hand the checks to Codex, a different model family from the one I run in MCode; Claude Code plus Codex works too. The gap check and the final verification must come from the family that didn’t do the work, through a CLI that’s installed and logged in.
- Node.js 24, git, and
ghorglab. - An app the agent can start, operate and observe from a worktree (phase A). The repository readiness guide in dev-skills covers what that takes, and Lauren’s create-verification-skill is a good place to start.
- core-grill asks its questions. Answer them and confirm the decision summary.
- core-spec writes spec and verify and has the other family check them for gaps. Read the result and confirm. It freezes both files and opens a draft PR.
- deliver works until the PR is mergeable. Read the decision list at the top, then merge.
$ instead of /.
Sources
OpenAI- Harness engineering: leveraging Codex in an agent-first world, Ryan Lopopolo (@_lopopolo)
- Using PLANS.md for multi-hour problem solving (ExecPlans)
- Codex skill-creator
- Effective harnesses for long-running agents
- Harness design for long-running application development
- Building effective agents
- Building multi-agent systems: when and how to use them
- Claude Code best practices
- The Complete Guide to pstack, Pt. 1
- pstack guide
- pstack skills and playbooks: poteto-mode (feature, orchestrate, session-pickup), principle-encode-lessons-in-structure, create-verification-skill
- pstack PR #419
- Her talk on X (September 2026)